Navigating the Currents of Data Infrastructure Evolution
The world of data storage is anything but static; it is a domain of relentless innovation and rapid evolution, driven by the insatiable demands of big data and analytics. Keeping a finger on the pulse of the latest Storage In Big Data Market Trends is crucial for any organization aiming to build a future-proof, cost-effective, and high-performance data infrastructure. These trends are not fleeting fads but significant shifts in technology, architecture, and strategy that are fundamentally reshaping how we store, manage, and access information at scale. They reflect the industry's response to the persistent challenges of data growth, the performance requirements of new workloads like AI, and the economic pressures of managing petabyte-scale environments. From the unstoppable rise of cloud object storage to the convergence of data lakes and warehouses, these trends provide a clear indication of where the market is heading. Understanding them allows businesses to make smarter investment decisions, avoid obsolete technologies, and position themselves to take full advantage of the next wave of data-driven opportunities.
The Unstoppable Dominance of Cloud Object Storage
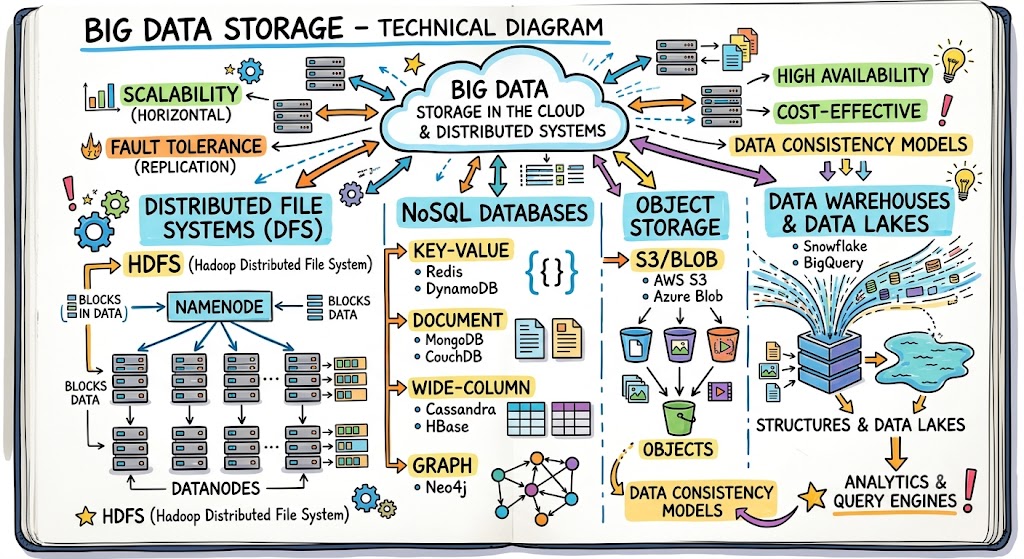
Perhaps the single most dominant trend in big data storage is the mass migration towards cloud object storage services like Amazon S3, Azure Blob Storage, and Google Cloud Storage. Originally seen as a cheap and deep archive, object storage has evolved to become the primary storage layer for a vast array of modern applications, most notably as the foundation for data lakes. Its key attributes—virtually limitless scalability, exceptional durability, low cost, and a simple HTTP-based API—make it perfectly suited for the unstructured and semi-structured data that constitutes the bulk of big data. This trend is accelerating as more analytics and AI/ML platforms are being re-architected to work directly and performantly with data residing in object storage. The de facto standardization of the S3 API has further fueled this trend, with on-premise storage vendors and open-source projects now offering S3-compatible solutions, enabling hybrid cloud strategies. The move to object storage represents a fundamental architectural shift away from traditional, block-based file systems for large-scale data repositories, and its dominance is only set to grow as more data is born in and moves to the cloud.
The Rise of NVMe and Flash for High-Performance Workloads
While object storage is ideal for capacity and scale, a parallel trend is catering to the need for speed. The rise of demanding workloads like real-time analytics, machine learning model training, and high-frequency trading has created a booming demand for ultra-high-performance storage. This trend is being driven by the adoption of flash storage (SSDs) and, more specifically, the NVMe (Non-Volatile Memory Express) protocol. NVMe was designed from the ground up for flash memory, bypassing the bottlenecks of older protocols like SATA and SAS that were created for spinning disks. It allows for massively parallel communication between the CPU and the SSDs, resulting in drastically lower latency and higher IOPS (Input/Output Operations Per Second). This trend is now extending beyond the server with NVMe-oF (NVMe over Fabrics), which allows the high performance of NVMe to be shared across a network, creating high-performance, scale-out storage pools. As the price of flash continues to decrease and the data demands of AI/ML continue to increase, the trend of using all-flash, NVMe-powered storage for the "hot" tier of big data workloads will become increasingly mainstream, providing the speed necessary to fuel the most advanced analytical applications.
The Convergence of Data Lakes and Warehouses (The "Lakehouse")
For years, organizations operated with a two-tiered data architecture: a data lake for cheap, flexible storage of raw data, and a separate data warehouse for reliable, high-performance analytics on structured data. The process of moving and transforming data between these two silos (ETL) was complex, costly, and created data redundancy. A major emerging trend is the convergence of these two concepts into a single architecture known as the "Data Lakehouse." The goal of the lakehouse is to provide the performance, reliability, and governance features of a data warehouse directly on top of the low-cost, open object storage of a data lake. This is enabled by new open-source technologies and table formats like Delta Lake, Apache Iceberg, and Apache Hudi. These formats add a transactional layer to object storage, providing ACID (Atomicity, Consistency, Isolation, Durability) transactions, data versioning (time travel), and schema enforcement. This trend is profoundly disruptive, as it promises to eliminate the need for separate, siloed data systems, simplifying data architecture, reducing costs, and ensuring that all users, from data scientists to business analysts, are working from a single, consistent source of truth.
Intelligent Data Management and Automated Tiering
As data volumes explode, manually managing where data resides becomes an impossible task. A critical trend is the infusion of intelligence and automation into the storage management layer. Modern storage platforms are increasingly incorporating AI and machine learning to automate complex data management tasks, with a primary focus on cost optimization. The most prominent application of this is automated data tiering. An intelligent storage system can automatically monitor the access patterns of every piece of data. Data that is frequently accessed (hot data) is automatically kept on expensive, high-performance flash storage. As data becomes less frequently accessed (warm or cold), the system automatically and transparently moves it to lower-cost tiers, such as capacity-oriented HDDs or even deep archive cloud storage like Amazon Glacier. This ensures that performance is available when needed, while the total cost of storage is minimized. This trend extends beyond tiering to include automated data placement for compliance, intelligent capacity planning, and even predictive hardware failure analysis. This move towards an "autonomous" storage infrastructure is essential for managing the complexity and cost of multi-petabyte environments.
➤ Featured Insights from Market Research Future: