Feature engineering is an important part of machine learning because it helps algorithms understand data more effectively and produce reliable predictions. Raw datasets often contain missing values, irrelevant details, and complex information that models cannot interpret efficiently. By transforming existing data into meaningful features, developers can improve model performance and uncover relationships that might otherwise remain hidden. Learning these techniques through practical projects helps aspiring professionals develop stronger data science skills.
Understanding the Role of Feature Engineering in Machine Learning
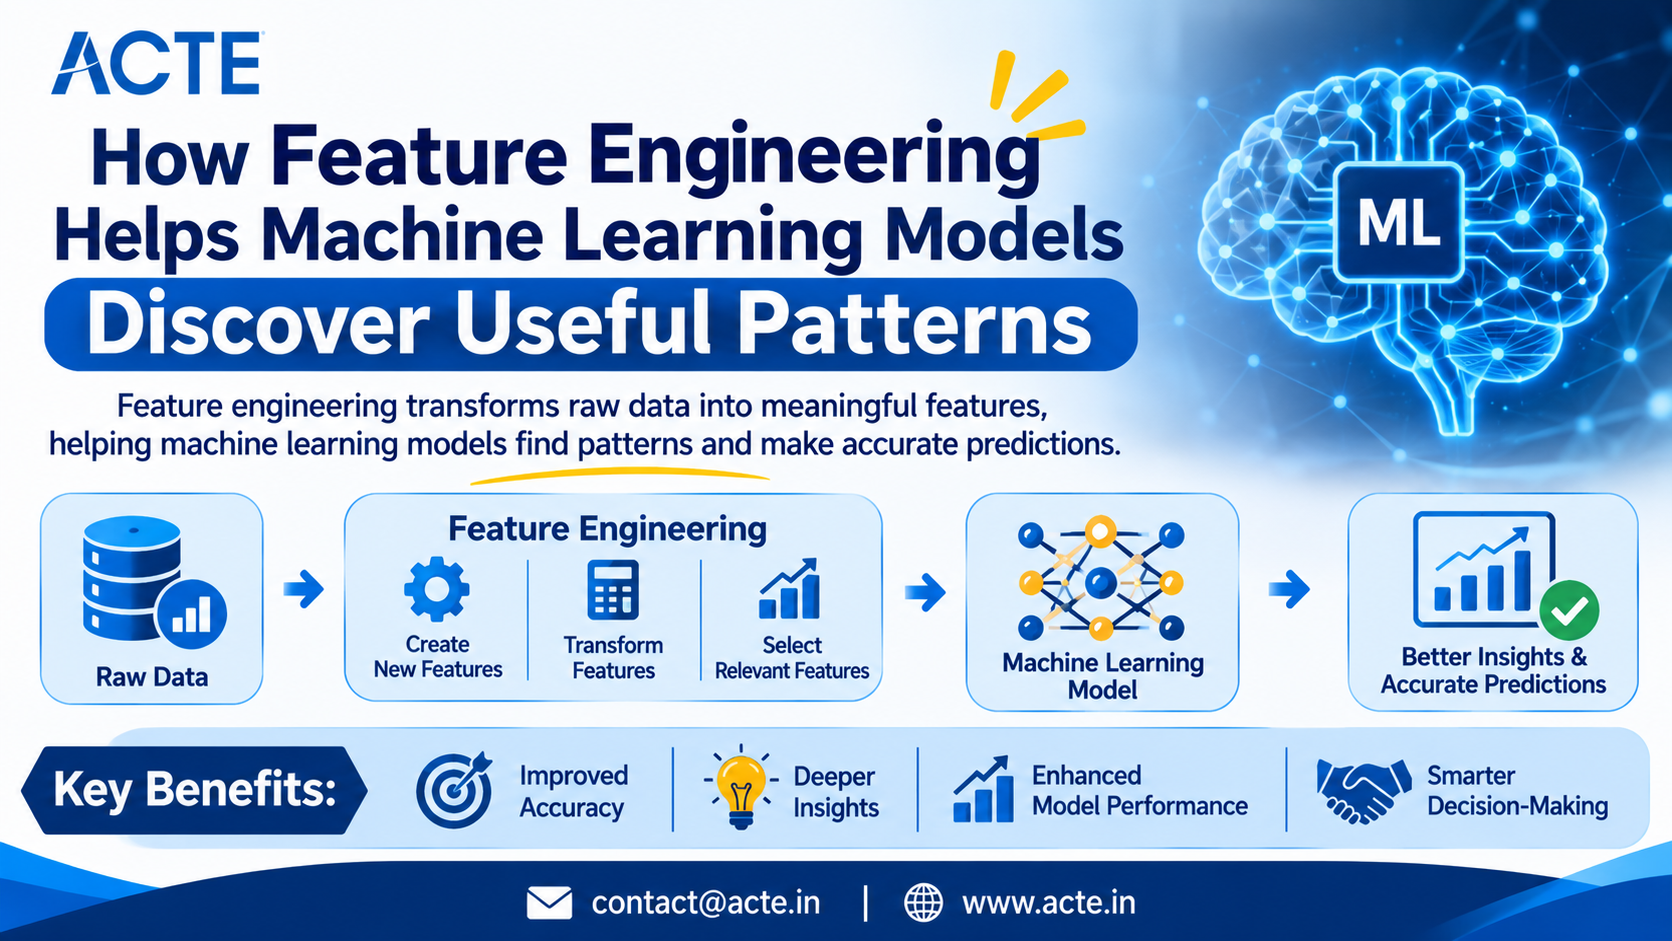
Feature engineering involves selecting, modifying, and creating data attributes that help machine learning algorithms identify useful patterns. The quality of these features directly influences how effectively a model learns from its training data. Well-prepared features can improve prediction accuracy, reduce unnecessary complexity, and make model outputs easier to interpret. Professionals pursuing a Data Science and AI Training in Chennai program can develop an understanding of these concepts through practical learning and real-world exercises.
Preparing Raw Data for Better Model Interpretation
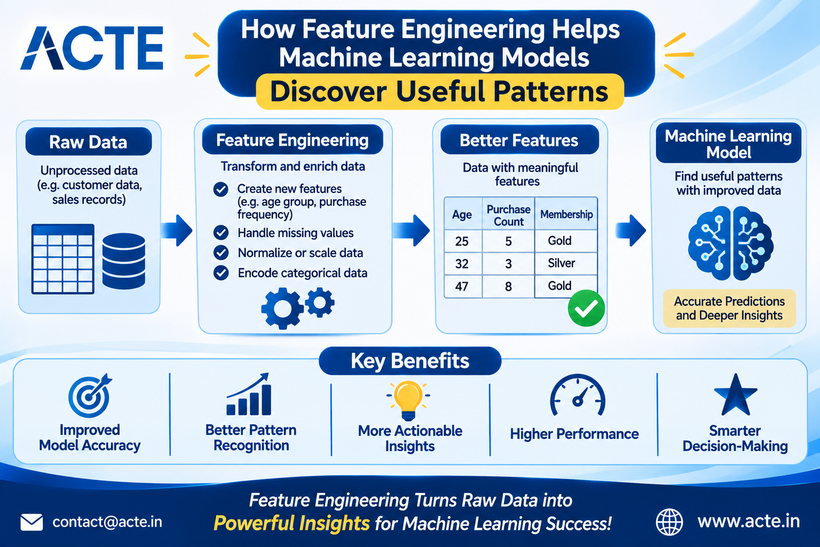
Raw datasets frequently include duplicate records, inconsistent formats, missing values, and unrelated information. These issues can affect the learning process and reduce the reliability of predictions. Data cleaning and transformation techniques help organize information into a consistent structure. Handling missing values, converting categorical variables, scaling numerical attributes, and removing unnecessary columns are common feature preparation activities. Properly processed data allows machine learning algorithms to identify relationships more efficiently.
Creating Meaningful Features from Existing Information
Feature creation helps developers generate additional attributes by combining or transforming existing data. For example, a transaction date can be converted into useful features such as month, weekday, or purchase season. Similarly, customer purchase records can be used to calculate average spending and buying frequency. These newly created attributes provide additional context that helps algorithms recognize patterns. Learners exploring a Data Science and AI Course in Bangalore can understand how feature creation supports different predictive modeling applications.
Selecting Relevant Features to Improve Model Accuracy
Using every available attribute does not always produce better machine learning results. Irrelevant or repetitive features can increase computational requirements and introduce unnecessary noise. Feature selection techniques help identify the attributes that contribute most to prediction quality. Methods such as correlation analysis, statistical testing, and feature importance evaluation support this process. Selecting meaningful variables can simplify models, improve processing efficiency, and reduce the possibility of overfitting.
Applying Feature Engineering Across Different Industries
Feature engineering supports machine learning applications in healthcare, finance, retail, manufacturing, and marketing. Healthcare systems use patient information to identify potential risk factors, while financial institutions analyze transaction patterns to detect suspicious activities. Retail businesses create customer behavior features to improve product recommendations and demand forecasting. These applications demonstrate how transforming raw information into useful attributes can support practical business decisions.
Using Python Libraries for Effective Feature Development
Python provides several libraries that simplify feature engineering tasks. Pandas helps organize and transform datasets, while NumPy supports numerical operations and calculations. Scikit-learn provides preprocessing tools for encoding categorical variables, scaling numerical data, and selecting important features. Matplotlib and Seaborn help visualize relationships and understand data distributions. Professionals pursuing a Data Science and AI Course in Hyderabad can gain practical experience using these tools to prepare datasets for machine learning projects.
Building Practical Machine Learning Skills Through Projects
Working on real-world projects helps learners understand how feature engineering influences model performance. Projects involving customer segmentation, sales forecasting, fraud detection, and loan approval prediction provide opportunities to clean datasets, create useful variables, and evaluate feature importance. Comparing model results before and after feature engineering also helps demonstrate its impact. A structured Data Science and AI Course can help learners strengthen these abilities through practical assignments and industry-focused projects.
Conclusion:
Feature engineering helps machine learning models discover meaningful relationships by converting raw information into useful attributes. Data preparation, feature creation, and feature selection all contribute to improving model efficiency and prediction quality. Understanding these techniques enables aspiring professionals to build more effective machine learning solutions and address real-world challenges. With consistent practice and hands-on project experience, learners can develop the technical knowledge required for careers in data science and artificial intelligence.